# Connect Reverse ETL Source to Customer.io Audience

<p>This guide takes you through the steps to connect a Reverse ETL source to the Customer.io Audience destination. You can create a new segment or use an existing segment to sync the data.</p>
<p>The below steps assume that you have already <a href="https://www.rudderstack.com/docs/sources/reverse-etl/" >set up a Reverse ETL source</a> and <a href="https://www.rudderstack.com/docs/destinations/reverse-etl-destinations/customerio-audience/setup-guide/#connection-settings" >configured the connection settings</a> for the connected Customer.io Audience destination.</p>

<blockquote class="success">
  <div class="tip-quote">
    
    <div class="tip-text">
      You can connect multiple Reverse ETL sources to the Customer.io Audience destination.
    </div>
  </div>
</blockquote>
<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="customerio-segment-settings">Customer.io segment settings</h2><table>
  <thead>
      <tr>
          <th>Setting</th>
          <th>Description</th>
      </tr>
  </thead>
  <tbody>
      <tr>
          <td>Choose whether to create a new Customer.io Segment</td>
          <td>Specify whether you want to sync data to a new or existing Customer.io segment. <br /><br /><ul><li>If you select <strong>Create a new Customer.io Manual Segment</strong>, then specify the name and description (optional) for the new segment.</li><li>Select <strong>Use an existing Customer.io Manual Segment</strong> if you have an existing Customer.io segment. Then, choose the list automatically prepopulated by RudderStack based on your specified <a href="https://www.rudderstack.com/docs/destinations/reverse-etl-destinations/customerio-audience/setup-guide/#connection-settings" >connection settings</a>.</td>
      </tr>
      <tr>
          <td>Sync mode</td>
          <td>RudderStack supports only <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-modes/#mirror-mode" >Mirror mode</a> for this integration.</td>
      </tr>
  </tbody>
</table>
<!-- end-chunk -->
<!-- begin-chunk -->
<h3 id="mapping-settings">Mapping settings</h3>
<blockquote class="warning">
  <div class="tip-quote">
    
    <div class="tip-text"><p>Make sure that the users exist in Customer.io before adding them to any segment. Otherwise, such records will be ignored.</p>
<p>See the <a href="https://docs.customer.io/journeys/segments/#troubleshooting-segments" >Customer.io Troubleshooting</a> guide for more information.</p>
</div>
  </div>
</blockquote>
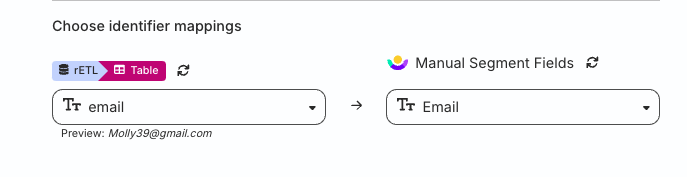
<p>Use this section to map the identifier warehouse column (that RudderStack uses to identify your records) to specific Customer.io segment fields. Note that you can map this warehouse column to either of these Customer.io segment fields: <strong>ID</strong>, <strong>Email</strong>, or <strong>CIO_ID</strong>.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/event-stream-destinations/customerio-audience-mappings.webp"
        
        >
        <img src="/docs/images/event-stream-destinations/customerio-audience-mappings.webp" 


        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<!-- end-chunk -->
<!-- begin-chunk -->
<h3 id="schedule-settings">Schedule settings</h3>

<p>RudderStack determines how and when to run a sync based on the <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-schedule-settings/" >sync schedule</a> you set for your Reverse ETL connection.</p>
<table>
  <thead>
      <tr>
          <th>Schedule type</th>
          <th>Description</th>
      </tr>
  </thead>
  <tbody>
      <tr>
          <td>Basic</td>
          <td>Run syncs at a set interval, optionally starting from a specified time (UTC). <br /><br />If a start time is set, syncs run from that time until the end of that day.</td>
      </tr>
      <tr>
          <td>CRON</td>
          <td>Run syncs based on a specified CRON expression (in UTC).</td>
      </tr>
      <tr>
          <td>Manual</td>
          <td>Run syncs manually.</td>
      </tr>
  </tbody>
</table>
<!-- end-chunk -->
<!-- begin-chunk -->
<h3 id="sync-observability-settings">Sync observability settings</h3>

<table>
  <thead>
      <tr>
          <th>Setting</th>
          <th>Description</th>
      </tr>
  </thead>
  <tbody>
      <tr>
          <td>Retain sync logs</td>
          <td>This setting is toggled on by default and instructs RudderStack to store the sync logs in your warehouse. You can also configure the below settings: <br /><br /><table><tr><th width="20%">Setting</th><th width="80%">Description</th></tr><tr><td>Sync log retention</td><td>Specify the retention period of the <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-observability/#sync-logs" >sync logs</a> in your warehouse. <br /><br />If you set it to 1, then RudderStack deletes any sync log older than a day (in UTC time). </td></tr><tr><td>Snapshot table retention</td><td>Specify the number of <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-observability/#snapshot-table-schema" >snapshot tables</a> to retain. </td></tr></table></td>
      </tr>
      <tr>
          <td>Retry failed records</td>
          <td>This setting is toggled on by default and causes RudderStack to continually <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-observability/#retry-failed-records" >retry sending the failed records</a>.</td>
      </tr>
      <tr>
          <td>Retain and show failures</td>
          <td>This setting is toggled off by default. Turn it on to have RudderStack write the error recorded for every failed record to a <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/rudderstack-schema/#failed-records-table" >failed records table</a> in your warehouse and show it in the sync&rsquo;s <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-observability/#failed-records" >failed records view</a>. It applies from the next sync and can take up to a minute to reach your data plane. <br /><br /><table><tr><th width="20%">Setting</th><th width="80%">Description</th></tr><tr><td>Failure retention</td><td>Number of days RudderStack keeps each sync&rsquo;s failed records in your warehouse. The default is 30 and the minimum is 7.</td></tr></table></td>
      </tr>
  </tbody>
</table>

<blockquote class="warning">
  <div class="tip-quote">
    
    <div class="tip-text">Storing sync logs, snapshot tables, and failed records may incur additional warehouse costs.</div>
  </div>
</blockquote>

<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="record-event-structure"><code>record</code> event structure</h2><p>The Customer.io Audience destination supports only <code>record</code> events.</p>
<p>A sample <code>record</code> event that RudderStack sends to Customer.io segments is shown:</p>
<div class="rs-code">
  <div class="rs-code__head">json<button class="rs-code__copy" type="button">
      
      Copy
    </button>
  </div>
  <div class="highlight"><pre class="chroma"><code class="language-json" data-lang="json">{
  &#34;action&#34;: &#34;insert&#34;,
  &#34;channel&#34;: &#34;sources&#34;,
  &#34;context&#34;: {
    &#34;sources&#34;: {
      &#34;job_id&#34;: &#34;&lt;2s4ZjYKSKztME0SmfBUB5t8KA3j&gt;&#34;,
      &#34;job_run_id&#34;: &#34;cu9na4c7miqjfjeogkv0&#34;,
      &#34;task_run_id&#34;: &#34;cu9na4s7miqjfjeogkvg&#34;,
      &#34;version&#34;: &#34;local&#34;
    }
  },
  &#34;fields&#34;: {},
  &#34;identifiers&#34;: {
    &#34;id&#34;: “30”
  },
  &#34;messageId&#34;: &#34;57f32b79-f030-4bdc-8f24-4f573f4acf99&#34;,
  &#34;receivedAt&#34;: &#34;2025-01-24T11:10:58.799Z&#34;,
  &#34;recordId&#34;: &#34;4&#34;,
  &#34;request_ip&#34;: &#34;[::1]&#34;,
  &#34;rudderId&#34;: &#34;0afd110a-4d8a-42c5-a959-05d3ef3b4e87&#34;,
  &#34;type&#34;: &#34;record&#34;,
  &#34;userId&#34;: &#34;36b9732a-cd10-4aec-b03e-36969a9b14a2&#34;
}</code></pre></div>
</div>
<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="faq">FAQ</h2><!-- end-chunk -->
<!-- begin-chunk -->
<h4 id="why-cant-i-add-a-reverse-etl-source-from-the-destination-page">Why can&rsquo;t I add a Reverse ETL source from the destination page?</h4><p>The Reverse ETL feature supports only source-driven pipeline configuration. It means that you must configure a Reverse ETL source in RudderStack and then connect it to a new or existing destination. Note that this destination should not be connected to any other source.</p>
<p>See <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/faq/" >Reverse ETL FAQ</a> for more information.</p>

