# Reverse ETL Quickstart Guide

<p>The easiest way to set up a Reverse ETL pipeline is to configure your warehouse source, connect it to a downstream destination, and specify the data mappings and sync settings.</p>

<html lang="en">
<blockquote class="info">
  <div class="tip-quote">
    
    <div class="tip-text"><p>You can set up to:</p>
<ul>
<li>10 connections in the RudderStack <a href="https://rudderstack.com/pricing/" >Free</a> plan</li>
<li>25 connections in the <a href="https://rudderstack.com/pricing/" >Growth</a> plan</li>
<li>Unlimited connections in the <a href="https://www.rudderstack.com/enterprise-quote/" >Enterprise</a> plan</li>
</ul></div>
  </div>
</blockquote>

</html>
<p>For most use cases, you can set up and activate your Reverse ETL pipeline by following these steps:</p>
<ol>
<li><a href="#step-1-add-source" >Add a source</a></li>
<li><a href="#step-2-connect-destination" >Add destination</a></li>
<li><a href="#step-3-create-mappings" >Define mappings</a></li>
<li><a href="#step-4-schedule-syncs" >Schedule syncs</a></li>
<li><a href="#step-5-activate-connection" >Activate connection</a></li>
</ol>
<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="step-1-add-source">Step 1: Add source</h2>
<html lang="en">
<blockquote class="info">
  <div class="tip-quote">
    
    <div class="tip-text">RudderStack lets you set up a Reverse ETL source from a warehouse table, <a href="https://www.rudderstack.com/docs/activate/models/" >Model</a>, or <a href="https://www.rudderstack.com/docs/activate/audiences/" >Audience</a>.</div>
  </div>
</blockquote>

</html>

<ol>
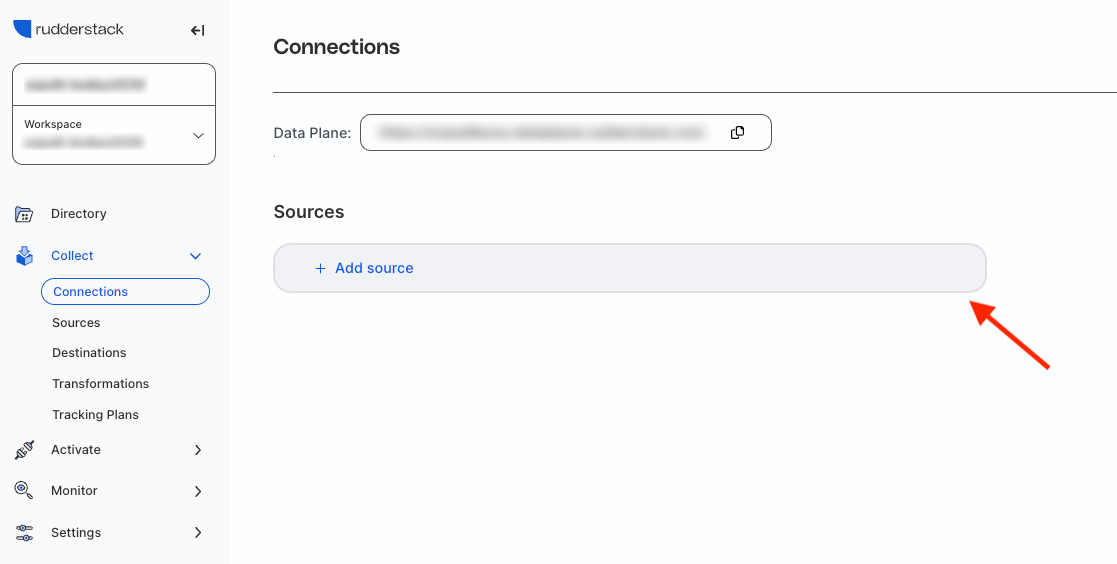
<li>Sign in to your <a href="https://app.rudderstack.com/" >RudderStack dashboard</a> and click <strong>+ Add source</strong> in the default <strong>Connections</strong> view.</li>
</ol>

<figure class="image--main "  >
    <a 
         href="/docs/images/get-started/quickstart/add-source.webp"
        
        >
        <img src="/docs/images/get-started/quickstart/add-source.webp" 
         alt="Add source"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<ol start="2">
<li>Under <strong>Sources</strong>, click <strong>Reverse ETL</strong> and select your warehouse source.</li>
<li>Configure your source. See the <a href="https://www.rudderstack.com/docs/sources/reverse-etl/#supported-reverse-etl-sources" >source-specific documentation</a> for configuration details.</li>
</ol>

<blockquote class="warning">
  <div class="tip-quote">
    
    <div class="tip-text"><p>RudderStack requires some warehouse-specific permissions to sync data from it. These permissions are listed in the source documentation, for example, see <a href="https://www.rudderstack.com/docs/sources/reverse-etl/google-bigquery/#granting-permissions" >BigQuery permissions</a>.</p>
<p>Make sure to grant these permissions <strong>before</strong> you set up the source.</p>
</div>
  </div>
</blockquote>

<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="step-2-connect-destination">Step 2: Connect destination</h2><p>Once you have set up the Reverse ETL source, the next step is to connect it to a downstream destination.</p>

<blockquote class="success">
  <div class="tip-quote">
    
    <div class="tip-text">
      RudderStack supports syncing data to over 200 <a href="https://www.rudderstack.com/docs/destinations/streaming-destinations/" >Event Stream</a> and <a href="https://www.rudderstack.com/docs/destinations/reverse-etl-destinations/" >Reverse ETL-only</a> destinations.
    </div>
  </div>
</blockquote>
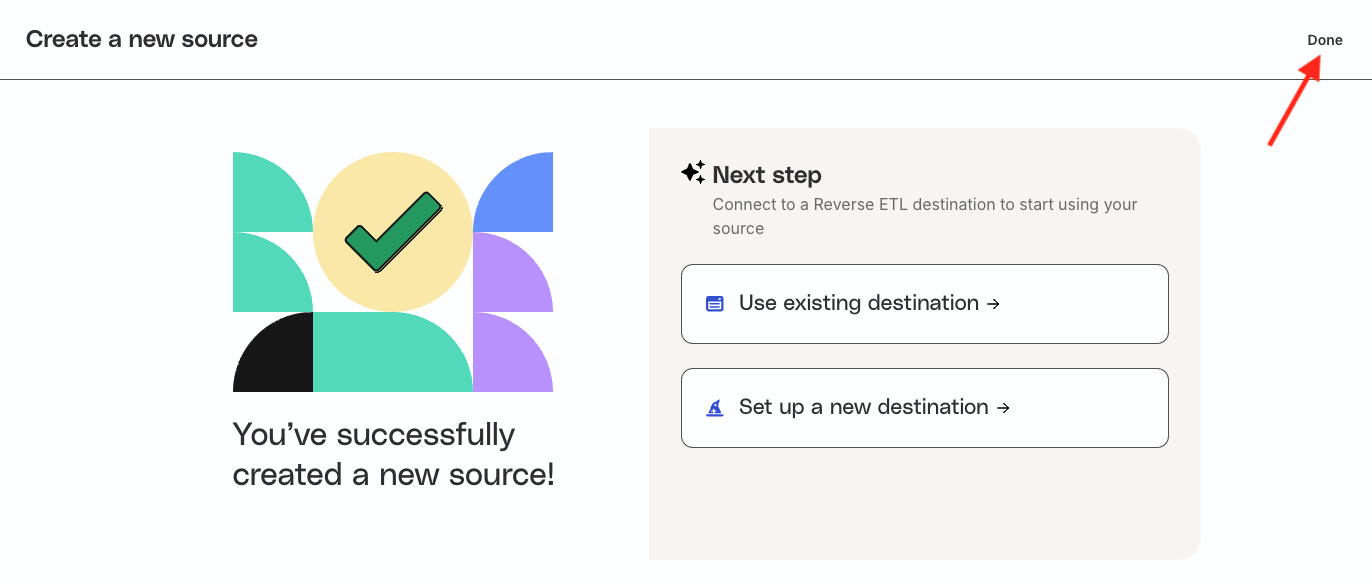
<p>You can connect the Reverse ETL source to an existing or new <a href="https://www.rudderstack.com/docs/destinations/overview/" >destination</a> to start using it. To connect to a destination later, click <strong>Done</strong> on the top right.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/retl-sources/created-source.webp"
        
        >
        <img src="/docs/images/retl-sources/created-source.webp" 
         alt="Next steps"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

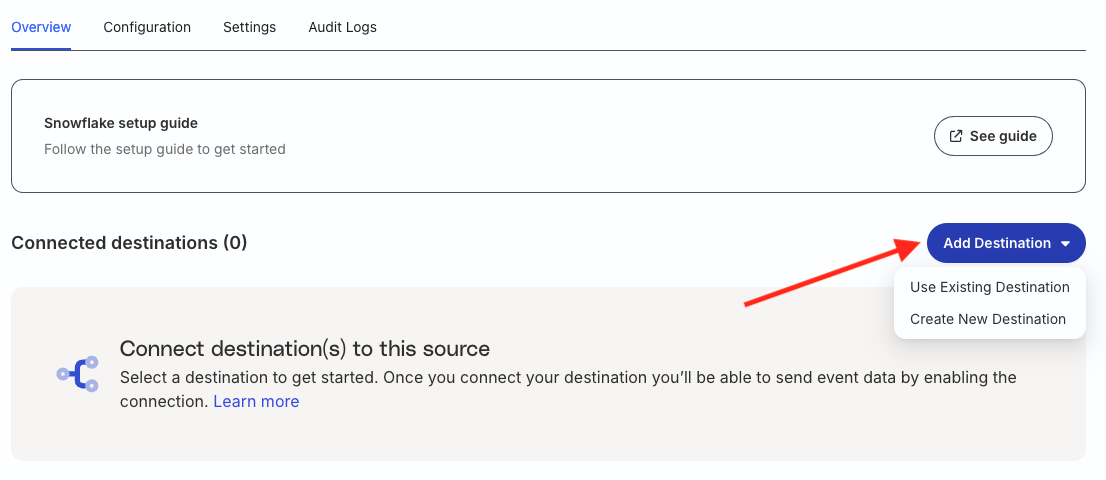
<p>You will then be redirected to the <strong>Overview</strong> page of the source where you get the option of connecting it to an existing or new destination.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/retl-sources/add-destination.webp"
        
        >
        <img src="/docs/images/retl-sources/add-destination.webp" 
         alt="Add destination"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<p>See <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/retl-connection-setup/" >Set Up Reverse ETL Connection</a> for more information.</p>
<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="step-3-create-mappings">Step 3: Create mappings</h2>

<p>RudderStack provides two options to map your warehouse columns to specific destination fields before syncing your data:</p>
<ul>
<li><a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/visual-data-mapper/" >Map with Visualizer</a></li>
<li><a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/json-data-mapping/" >Map with JSON</a></li>
</ul>

<html lang="en">
<blockquote class="info">
  <div class="tip-quote">
    
    <div class="tip-text"><p>RudderStack supports the <strong>Map with Visualizer</strong> option only for <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/visual-data-mapper/#supported-destinations" >selected destinations</a>.</p>
<p>Other destinations that do not support Visual Data Mapper have the <strong>Map with JSON</strong> option by default, with the <strong>Map with Visualizer</strong> option greyed out.</p>
</div>
  </div>
</blockquote>

</html>
<p>The steps to set the data mappings (using JSON) are listed below:</p>
<ol>
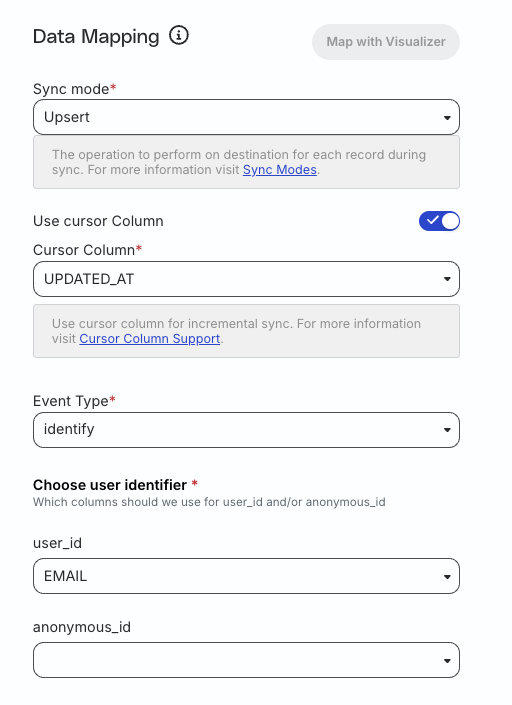
<li>Select the <strong>Sync mode</strong> to specify how RudderStack syncs each record to the destination. RudderStack supports two <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-modes/" >sync modes</a>:</li>
</ol>
<table>
  <thead>
      <tr>
          <th>Sync mode</th>
          <th>Description</th>
      </tr>
  </thead>
  <tbody>
      <tr>
          <td>Upsert</td>
          <td>In this mode, RudderStack inserts new records and updates the existing records in the destination while syncing the data.</td>
      </tr>
      <tr>
          <td>Mirror</td>
          <td>In this mode, RudderStack &lsquo;mirrors&rsquo; the source by keeping the destination data the same as the source data. It performs insertion, deletion, and updates to the records while syncing the data. <br /><br />Note that:<ul><li>Only <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-modes/#mirror-mode" >select destinations</a> support this mode.</li><li>RudderStack does not support <code>track</code> event type for this mode.</li><ul></td>
      </tr>
  </tbody>
</table>
<ol start="2">
<li>
<p>If you have set the sync mode to <strong>Upsert</strong>, you can also use the <strong>Use cursor column</strong> setting for managing incremental syncs. See <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/cursor-column-support/" >Cursor Column Support</a> guide for more information on this setting.</p>
</li>
<li>
<p>Select the <strong>Event Type</strong> - RudderStack supports sending the synced data to your downstream destinations as <code>identify</code> or <code>track</code> events.</p>
<ul>
<li>If you select <code>track</code> as the <strong>Event Type</strong>, you also need to set the event name that is sent to the downstream destination. This is because every <code>track</code> event requires a name.</li>
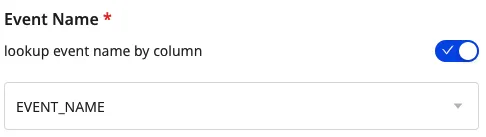
<li>You can also set the column name as the event name by turning on the <strong>Lookup event name by column</strong> toggle and selecting the column from the dropdown:</li>
</ul>
</li>
</ol>

<figure class="image--main "  >
    <a 
         href="/docs/images/warehouse-actions-sources/event-name-table-track.webp"
        
        >
        <img src="/docs/images/warehouse-actions-sources/event-name-table-track.webp" 
         alt="Schema tab options in RudderStack"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<ol start="3">
<li>Set at least one user identifier from <code>user_id</code> or <code>anonymous_id</code> in the <strong>Choose user identifier</strong> setting.</li>
</ol>

<figure class="image--main "  >
    <a 
         href="/docs/images/data-pipelines/map-with-json.webp"
        
        >
        <img src="/docs/images/data-pipelines/map-with-json.webp" 
         alt="Map with JSON feature"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<ol start="4">
<li>Preview the resulting data and make the necessary changes before proceeding.</li>
</ol>

<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="step-4-schedule-syncs">Step 4: Schedule syncs</h2>

<p>RudderStack determines how and when to run a sync based on the <a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/sync-schedule-settings/" >sync schedule</a> you set for your Reverse ETL connection.</p>
<table>
  <thead>
      <tr>
          <th>Schedule type</th>
          <th>Description</th>
      </tr>
  </thead>
  <tbody>
      <tr>
          <td>Basic</td>
          <td>Run syncs at a set interval, optionally starting from a specified time (UTC). <br /><br />If a start time is set, syncs run from that time until the end of that day.</td>
      </tr>
      <tr>
          <td>CRON</td>
          <td>Run syncs based on a specified CRON expression (in UTC).</td>
      </tr>
      <tr>
          <td>Manual</td>
          <td>Run syncs manually.</td>
      </tr>
  </tbody>
</table>
<!-- end-chunk -->
<!-- begin-chunk -->
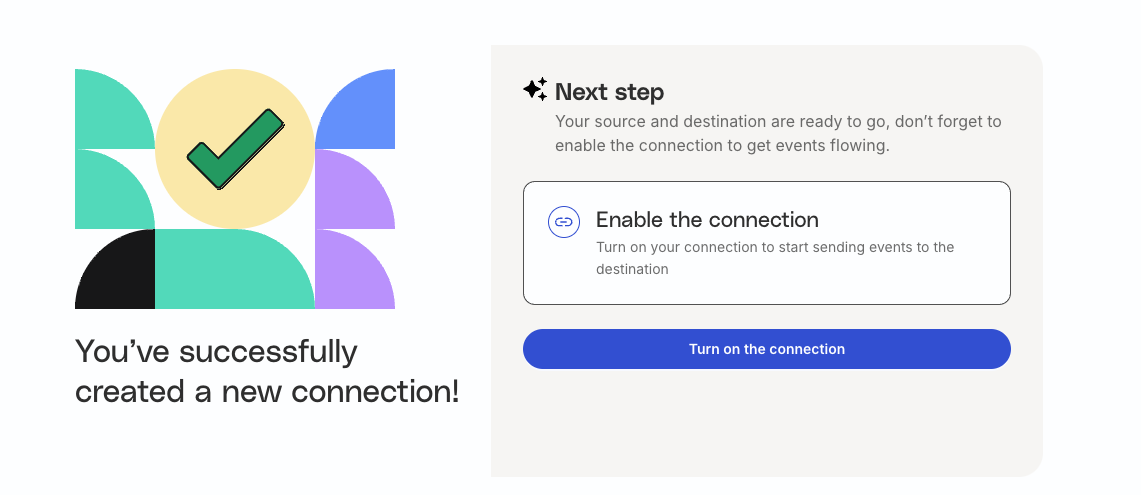
<h2 id="step-5-activate-connection">Step 5: Activate connection</h2><p>Once your source and destination are set up, activate the connection by clicking <strong>Turn on the connection</strong>.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/data-pipelines/turn-on-connection.webp"
        
        >
        <img src="/docs/images/data-pipelines/turn-on-connection.webp" 
         alt="Turn on Reverse ETL connection"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<p>Once you activate the connection, RudderStack automatically triggers the syncs as per the <a href="#step-4-schedule-syncs" >sync schedule</a>.</p>

<html lang="en">
<blockquote class="info">
  <div class="tip-quote">
    
    <div class="tip-text">When you sync data from the source for the first time, RudderStack performs a full sync by default, irrespective of the sync mode you specified while <a href="#step-3-create-mappings" >setting the mappings</a>. It then incrementally syncs any new data since the last sync.</div>
  </div>
</blockquote>

</html>
<!-- end-chunk -->
<!-- begin-chunk -->
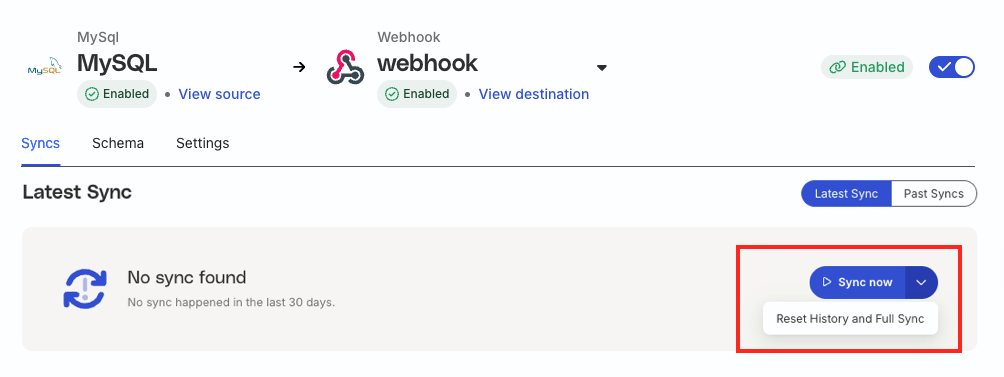
<h3 id="trigger-syncs">Trigger syncs</h3><p>Go to the <strong>Syncs</strong> tab of your Reverse ETL source and click the <strong>Sync Now</strong> button to trigger a new sync. To force a full data sync, choose the <strong>Reset History and Full Sync</strong> option.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/data-pipelines/trigger-full-sync.webp"
        
        >
        <img src="/docs/images/data-pipelines/trigger-full-sync.webp" 
         alt="Trigger new syncs"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

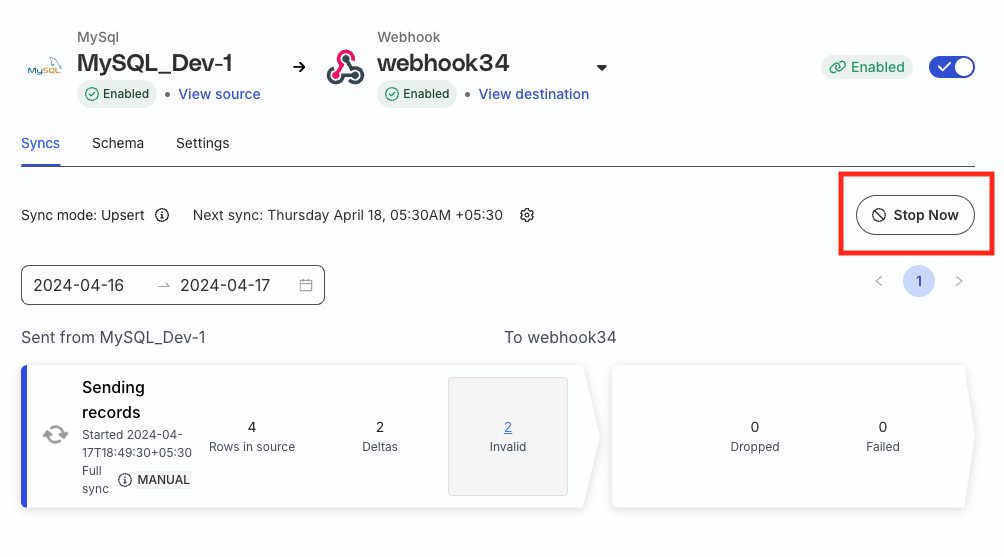
<p>To stop a running sync, click the <strong>Stop Now</strong> button.</p>

<figure class="image--main "  >
    <a 
         href="/docs/images/data-pipelines/stop-sync.webp"
        
        >
        <img src="/docs/images/data-pipelines/stop-sync.webp" 
         alt="Stop syncs"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<blockquote class="warning">
  <div class="tip-quote">
    
    <div class="tip-text"><p>Note the following before stopping a sync:</p>
<ul>
<li>Once you stop a sync, any data that RudderStack reads from the warehouse and is on the fly may not be stopped or dropped from being delivered to the destination. It will only stop reading and sending any new data from the warehouse to the destination and stop the sync from progressing.</li>
<li>For a very low number of deltas (new data since the last attempted sync), you may sometimes see a &ldquo;0 deltas succeeded&rdquo; after you stop the sync.</li>
<li>Once you cancel a sync, the behavior of the next sync depends on the type of the previously cancelled sync. For example, if a cancelled sync is an incremental sync, then the next sync will be incremental too. Similarly, if the cancelled is a full sync, then the next sync will be a full sync.</li>
</ul></div>
  </div>
</blockquote>
<!-- end-chunk -->
<!-- begin-chunk -->
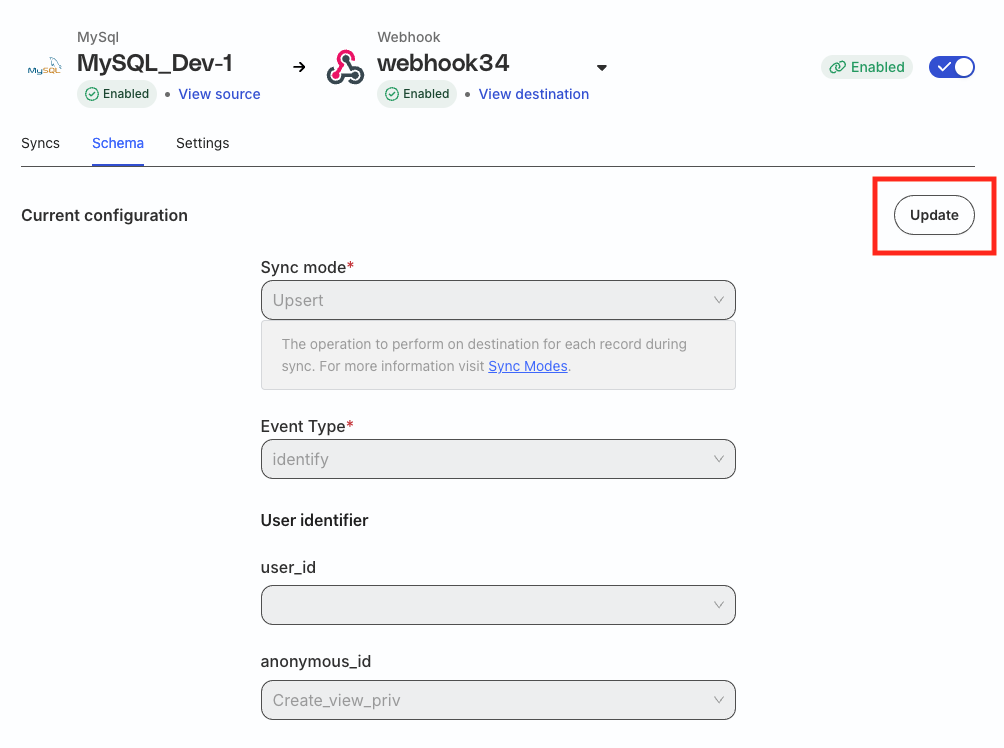
<h3 id="update-your-mappings">Update your mappings</h3><p>In cases where your warehouse schema has changed, RudderStack lets you update the mappings to ensure the data is synced to the destination correctly.</p>
<p>Go to the <strong>Schema</strong> tab of your connection page and click <strong>Update</strong> to update your mappings. Make sure to save the updated mappings.</p>

<blockquote class="warning">
  <div class="tip-quote">
    
    <div class="tip-text">You cannot update the mappings while a sync is in progress.</div>
  </div>
</blockquote>

<figure class="image--main "  >
    <a 
         href="/docs/images/data-pipelines/update-mappings.webp"
        
        >
        <img src="/docs/images/data-pipelines/update-mappings.webp" 
         alt="Update connection mappings"  
         
         
        decoding="async" loading="lazy" class="img-shortcode"/>
    </a>
    
</figure>

<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="sync-data-from-sql-models">Sync data from SQL models</h2><p>RudderStack&rsquo;s <a href="https://www.rudderstack.com/docs/activate/models/" >Models</a> feature lets you create models by defining custom SQL queries. You can then run these queries on your warehouse and send the resulting data to specific destinations.</p>
<p>Follow these steps to set up a Reverse ETL pipeline using a model:</p>
<ol>
<li><a href="https://www.rudderstack.com/docs/activate/models/create-model/" >Create a new model</a></li>
<li><a href="https://www.rudderstack.com/docs/activate/models/create-model/#connect-model-to-destination" >Connect the model to a destination</a></li>
<li><a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/json-data-mapping/" >Set up the data mappings</a></li>
</ol>
<!-- end-chunk -->
<!-- begin-chunk -->
<h2 id="sync-data-from-audiences">Sync data from Audiences</h2>

<blockquote class="announcement">
  <div class="tip-quote">
    
    <div class="tip-text"><p><strong>This Audiences feature leverages the Reverse ETL workflow.</strong></p>
<p>To build targeted, no-code audience segments from warehouse data and activate them downstream, use <a href="https://www.rudderstack.com/docs/activate/lookout/" >Rudder Lookout</a> instead.</p>
</div>
  </div>
</blockquote>

<p>RudderStack’s <a href="https://www.rudderstack.com/docs/activate/audiences/" >Audiences</a> feature lets you create customer lists or a subset of users satisfying specific criteria with easy-to-use filters on your warehouse tables. Once created, you can connect and activate them in your downstream destinations.</p>
<p>Follow these steps to set up a Reverse ETL pipeline using an audience:</p>
<ol>
<li><a href="https://www.rudderstack.com/docs/activate/audiences/create-audience/" >Set up a new audience</a></li>
<li><a href="https://www.rudderstack.com/docs/activate/audiences/create-audience/#connect-audience-to-destination" >Connect the audience source to a destination</a></li>
<li><a href="https://www.rudderstack.com/docs/data-pipelines/reverse-etl/developer-guides/json-data-mapping/" >Set up the data mappings</a></li>
</ol>
<br />